Document Intake and Filing Automation for Every Arrival
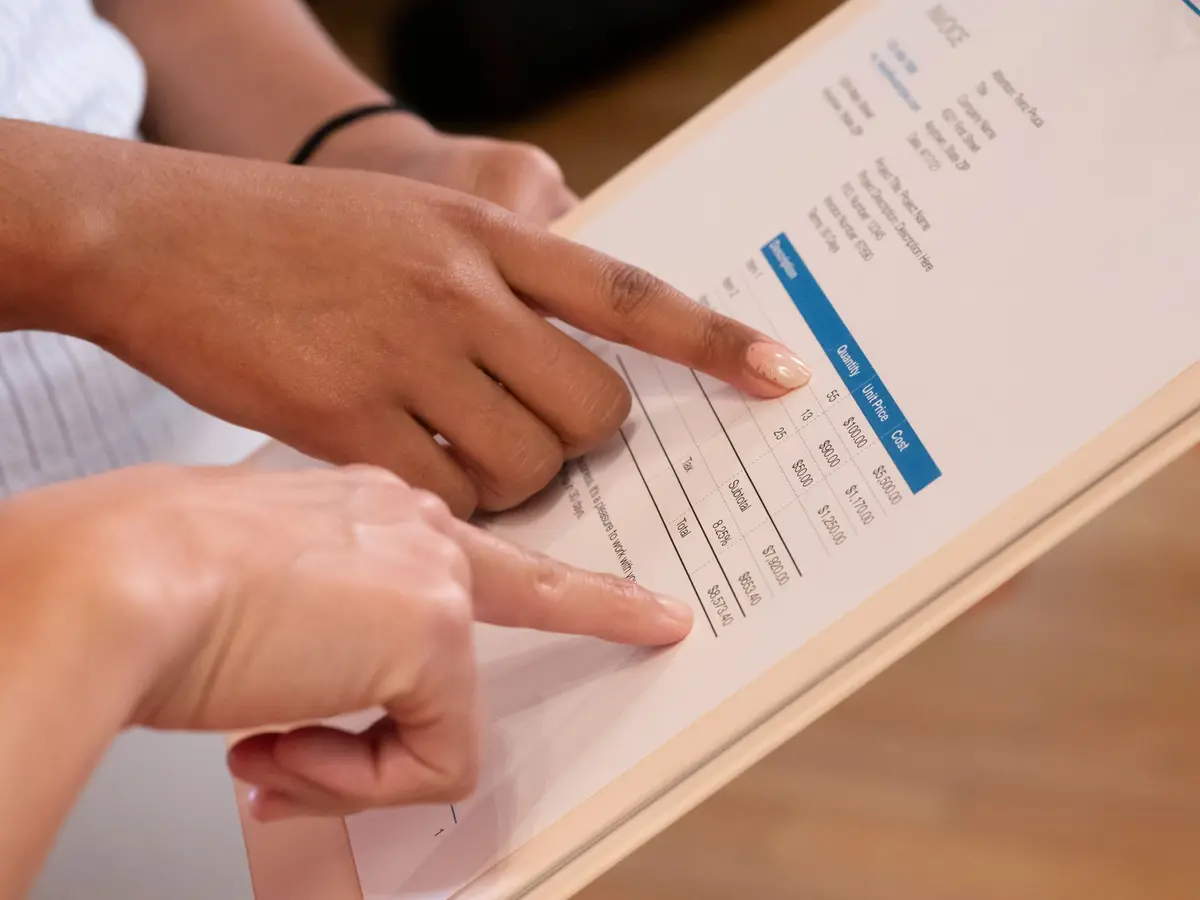
Document processing automation is a service that reads incoming documents (invoices, contracts, forms, receipts, ID scans, statements), classifies them, extracts the data, files them in the right folder or system with a consistent name, and triggers the next action, such as an approval request or an entry in your accounting software. It replaces the manual sorting, renaming and re-typing that staff currently do by hand. A well-built setup handles the routine, predictable share of your paperwork automatically and routes anything unclear or unusual to a person for a quick check, rather than trying to force every document through the machine.
In short
- The service reads, classifies, files and actions documents automatically, sending only unclear cases to a human reviewer.
- A parallel run against your current manual process comes before any manual step is switched off, so accuracy is proven first.
- Simple, single-document-type setups can go live in three to four weeks; multi-department rollouts typically take eight to twelve weeks.
- You provide real sample documents, system access and sign-off on exception rules; AiStaffo does not set your legal retention policy.
- The service is not worth building for low, irregular document volumes, and it never replaces the final human sign-off on payments, contracts or clinical decisions.
What this service is
Document intake and filing automation is a built and managed system that reads every document a business receives, whether by email, upload portal, scanner or shared drive, and turns it into a filed, named, and actioned record without a person typing it in by hand.
Who it is for
This fits businesses that receive a steady stream of paperwork and currently pay someone to open it, work out what it is, rename it, save it in the right place and pass it to the next person. Common cases include accounts payable teams buried in invoices, law and accounting firms handling client intake forms, property and insurance offices processing claims and applications, clinics and care providers managing patient forms, and logistics operators dealing with delivery notes and customs paperwork. It is not aimed at businesses receiving a handful of documents a week; the setup cost only pays for itself once volume and repetition are real.
What is included
- A document intake point: a dedicated email address, upload link or scanner folder that receives everything in one place
- Automatic reading of the document content using OCR and layout recognition, including scanned and handwritten pages where quality allows
- Classification: sorting each document into its correct type (invoice, contract, ID, claim form, statement, and so on)
- Consistent, rule-based file naming and folder placement across your existing storage or document management system
- Data extraction into structured fields that feed your accounting, CRM, ERP or practice management software directly
- Exception routing: anything the system cannot read with confidence goes to a named human reviewer with the reason flagged, rather than being guessed at
- Action triggers: an approval request, a task, a reminder or a status update fired automatically once a document is filed
- An audit trail showing what arrived, when it was read, who or what approved it and where it ended up
- A short reference guide for staff covering how to handle exceptions and how to add a new document type later
How it runs
1. Audit
We look at the document types you actually receive, in what volume, from which channels, and where they currently get stuck. This includes sitting with the people who open the post or the inbox today.
2. Process map
We map each document type from arrival to final action: who needs to see it, what data has to be pulled out, which system it must land in, and what counts as an exception worth a human look.
3. Build
We configure the reading, classification and extraction rules for your specific document types, connect the intake point to your storage and business systems, and set the naming and filing conventions.
4. Run
The system goes live on a subset of real, current documents first, in parallel with your existing manual process, so nothing is missed while accuracy is confirmed.
5. Support
Once confidence in the automated path is confirmed, manual handling is switched off for that document type and we monitor accuracy, retrain on new document formats, and adjust rules as your paperwork changes.
What the client provides
- Sample documents of each type you want automated, ideally 20 to 50 real examples per type, including messy or unusual ones
- Access to the systems the data needs to land in (accounting software, CRM, document management system, or shared drive)
- A named point of contact who can answer questions about how documents are currently handled and confirm business rules
- Decisions on file naming conventions and folder structure if you do not already have a standard
- Sign-off on the exception rules: what confidence level triggers a human check, and who that person is
Typical timeline
| Phase | Typical duration |
|---|---|
| Audit and process map | 1 to 2 weeks |
| Build and connect systems | 2 to 4 weeks |
| Parallel run and accuracy check | 1 to 3 weeks |
| Full switch-over and stabilisation | 1 to 2 weeks |
A single document type with a clean, consistent format can go live inside three to four weeks. A business automating several document types across departments, or connecting to older systems without a modern interface, should plan on eight to twelve weeks end to end.
What it does not cover
- It does not replace legal, financial or clinical judgement. A person still approves payments, signs off contracts and makes clinical decisions; the system prepares the information faster.
- It does not guarantee perfect reading of very poor scans, faint handwriting or heavily damaged documents. These are flagged as exceptions, not silently guessed.
- It does not set your document retention periods for you. Data protection rules such as the GDPR's storage limitation principle require you to justify how long you keep records, and requirements vary by document type and jurisdiction; we file according to the retention rules you confirm, we do not define your legal retention policy.
- It does not cover one-off or highly irregular document types received a handful of times a year. Automating these rarely earns back the setup effort.
- It does not include the underlying software licences for third-party systems you choose to connect to, if any are needed beyond what is already in place.
How AiStaffo would automate this
For document intake, AiStaffo connects your existing inbox, upload portal or scanner folder to a reading and classification layer, then wires the output directly into your accounting software, CRM or document management system, so a filed invoice or signed form updates the record it belongs to without anyone re-typing it. Naming and folder rules run automatically for every document type you approve, and anything the system is not confident about is routed to a named person with the reason attached, rather than filed blind. You still approve payments, sign contracts and make the calls that need judgement; AiStaffo removes the reading, sorting, renaming and re-entry around those decisions. Book a free automation audit.
Questions people ask
What document types can this handle?
What happens to documents the system cannot read confidently?
Do we need to change our existing folder structure or software?
How long does it take before we can turn off manual handling?
Does this replace our compliance or retention obligations?
Is this worth it for a small volume of documents?
Book a free automation audit
Thirty minutes. We look at one process you run every week and tell you exactly what an AI worker would take off your desk, and what it would not.